5 Dangerous Monitoring Blindspots and How to Fix Them
August 12, 2026
·8 min read
·
You check your monitoring dashboard, and every service indicator is flashing green. System status displays a reassuring 100% uptime. Yet, customer support tickets are trickling in, claiming the API is returning empty responses, or that users in Europe cannot connect to the service at all.
This scenario is far too common for modern software teams. Standard health checks frequently report that services are online when, in reality, end users are experiencing severe degradation or total outages.
Traditional active monitoring often relies on basic HTTP ping checks that verify whether a server is reachable and returning a success code. However, modern infrastructure—composed of microservices, distributed cloud environments, external API integrations, and background batch processing—is far too complex for surface-level checks.
In this article, we will examine 5 dangerous monitoring blindspots that plague production systems, explore practical real-world examples of how they cause outages, and discuss strategies to eliminate them.
1. The “HTTP 200 OK” Illusion (Shallow Health Checks)
The most widespread blindspot in health monitoring is relying exclusively on HTTP status codes.
A standard synthetic monitoring check sends an HTTP GET request to an endpoint (such as /health or /api/v1/status) and verifies that the web server responds with a 200 OK status within a reasonable timeout. While this confirms that your web web server or ingress proxy is running, it reveals almost nothing about whether your application logic is actually functioning.
The Real-World Failure Scenario
Consider an e-commerce checkout API service. When a user requests their cart data, the service queries a downstream database pool. If the database connection pool becomes completely exhausted due to a memory leak, the API framework might catch the unhandled internal error and return a formatted JSON payload:
{
  "success": false,
  "error": "Database connection pool exhausted",
  "data": null
}
Because the application server handled the error gracefully at the HTTP layer, it responds with an HTTP status code of 200 OK.
A basic monitoring tool will record this check as a success. Meanwhile, every single customer attempting to view their cart or complete a purchase encounters a broken user interface.
How to Fix It
To prevent shallow health check failures, your monitoring strategy must move beyond response status codes and evaluate actual response payloads:
Validate Response Bodies: Parse the return payload (such as JSON or XML) to verify that specific key-value pairs contain expected operational data.
Inspect Header Metadata: Ensure content-type headers match expectations and critical application tokens are present.
Implement Custom Assertion Scripts: Execute custom logical scripts against the response snapshot to perform conditional checks before determining whether an endpoint is genuinely healthy.
2. Neglecting Transport and Certificate Infrastructure (TCP & TLS)
Application-level checks (Layer 7) often obscure underlying issues at the network and transport layers (Layer 4). Engineers frequently assume that if an HTTPS web service is working today, the underlying network, DNS, and TLS certificates will continue operating smoothly tomorrow.
However, transport layer failure modes are among the most frequent causes of sudden, catastrophic downtime.
The Real-World Failure Scenario
Imagine a high-volume SaaS platform using an automated certificate manager. A renewal script encounters a rate limit or a misconfigured DNS challenge, failing to renew the TLS certificate before expiration.
If your monitoring tool only periodically pings the HTTP service without verifying certificate metadata, you will not receive an alert until the certificate officially expires. At that exact moment, every web browser and API client in the world abruptly terminates client connections due to an untrusted certificate chain (CERT_DATE_INVALID).
Similarly, monitoring tools that fail to break down connection phases miss subtle degradation patterns. An endpoint might still return data, but host resolution time (Time to DNS Resolved - TTDR) or initial connection time (Time to First Byte - TTFB) may spike drastically, signaling an impending network node failure.
Key Metrics to Track
Metric | Full Name | Operational Significance |
|---|---|---|
TTDR | Time to DNS Resolved | Identifies DNS provider latency, cache misses, or upstream lookup failures. |
TTFB | Time to First Byte | Measures server processing overhead and network round-trip delay before response delivery begins. |
RTT | Round Trip Time | Tracks complete end-to-end network latency for data transmission. |
TLS Expiry | Certificate Chain Validity | Proactively alerts teams days or weeks before a certificate chain expires or becomes invalid. |
3. Geographic and Routing Isolation
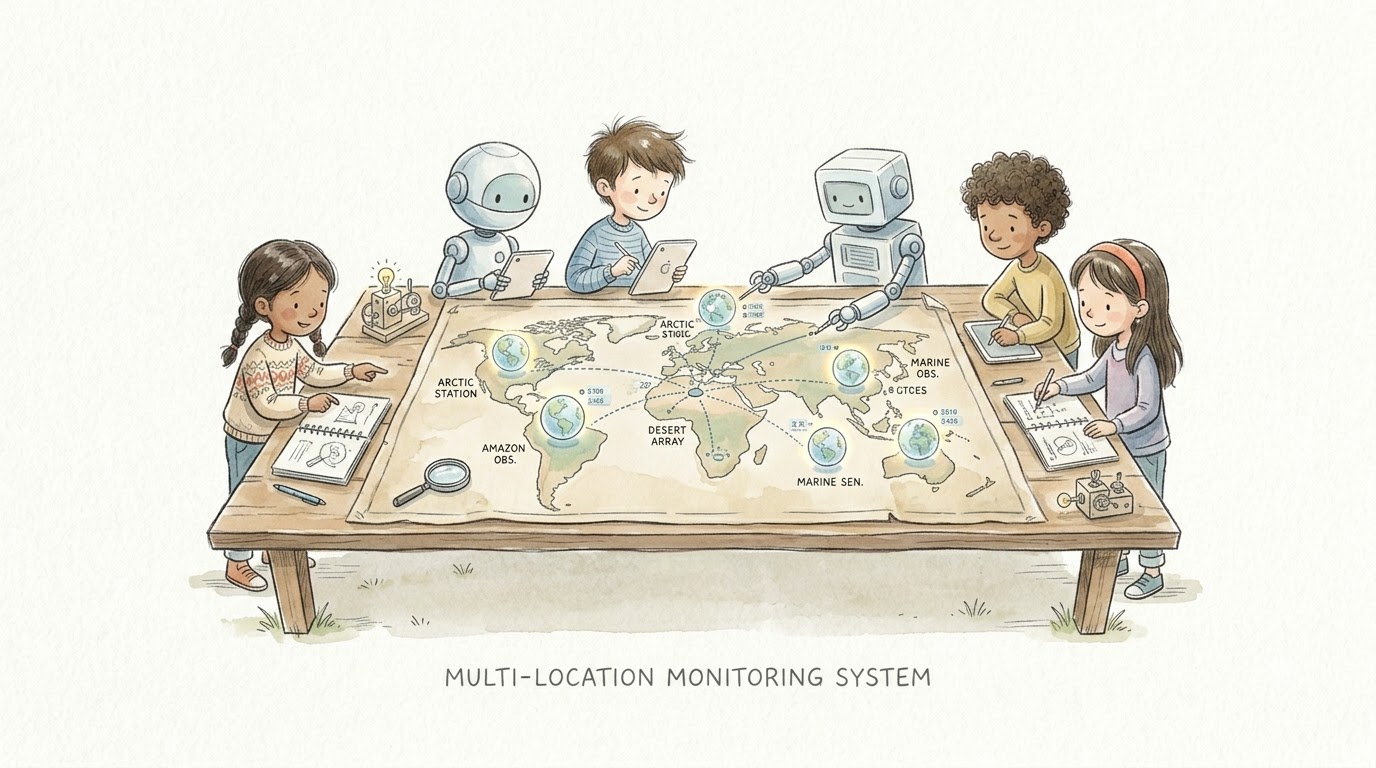
Testing your application solely from a single geographic server location creates a major blindspot. Localized network partitions, regional BGP routing glitches, and content delivery network (CDN) edge node failures routinely affect specific geographic regions while leaving others entirely untouched.
The Real-World Failure Scenario
Your primary application infrastructure and your monitoring agent are both hosted in a North American cloud data center. A core fiber link across the Atlantic experiences a physical break, or an Internet Service Provider (ISP) in Europe misconfigures its routing tables.
Users attempting to access your application from London, Frankfurt, or Paris experience request timeouts or DNS resolution errors.
Because your single monitoring probe resides in the same North American data center as your primary application host, all health checks pass cleanly. Your team remains completely unaware of a localized total outage affecting an entire continent until customer complaints flood your support channels.
+-------------------+             +-----------------------+
|  US Probe Agent   | -- (OK) --> | Primary Application   |
+-------------------+             | Infrastructure (US)   |
                                  +-----------------------+
                                              ^
+-------------------+                         |
| European Users    | -- (Connection Timeout) -+
+-------------------+
How to Fix It
Deploy Multi-Region Synthetic Probes: Execute concurrent health checks from multiple global locations—such as North America, Europe, Asia-Pacific, and Australia.
Correlate Regional Failures: Distinguish between global infrastructure failures (where all locations report down) and regional network routing failures (where only specific probe locations fail).
4. Unmonitored Non-HTTP Protocols
Modern infrastructure consists of far more than just standard HTTP/HTTPS REST APIs. Microservices rely heavily on raw TCP sockets, UDP communication, database protocols, message brokers, and specialized server protocols.
Focusing monitoring exclusively on web endpoints leaves essential backend components completely unmonitored.
The Real-World Failure Scenario
Consider an online gaming infrastructure or a real-time communications backend. The public marketing website and login API run on standard HTTP/HTTPS ports (80 and 443). However, real-time game state or media streams rely on custom TCP ports, raw UDP packet exchanges, or specialized game server protocols (such as the Minecraft server ping protocol).
If the backend game server process crashes while leaving the web-based management panel active:
HTTP monitoring tools report 100% uptime.
Players cannot connect to active game sessions.
System administrators receive zero automated alerts.
How to Fix It
A comprehensive active monitoring framework must natively support Layer 4 and non-HTTP protocols, allowing engineering teams to:
Verify raw TCP socket connections (e.g., checking database ports, SSH, or custom microservice ports).
Validate UDP packet delivery and response behaviors.
Test specialized application protocols natively without forcing developers to wrap internal services inside overhead-heavy HTTP wrapper endpoints.
5. Silent Failures in Scheduled Cron Tasks
Active synthetic monitoring excels at checking listening network endpoints. But what about background tasks that do not listen on a network port?
Modern application architectures rely heavily on cron jobs, scheduled worker tasks, database backup routines, and queue processors. These jobs run periodically, process data, and terminate. When a scheduled background task fails, it does so silently.
The Real-World Failure Scenario
A financial SaaS application executes a critical background task every night at 02:00 UTC to aggregate transaction logs, update user account balances, and compute daily billing statements.
Due to an unhandled null pointer exception introduced in a recent deployment, the job crashes immediately upon starting.
Because the job is a background process that does not host an exposed HTTP endpoint, standard synthetic probes never check it. The web API continues returning 200 OK. It takes three days before the finance team notices that billing statements were never generated, creating a major operational headache.
Expected Execution Path:
[02:00 UTC Scheduled Trigger] ---> [Job Starts] ---> [Process Data] ---> [Complete]
                                         |
Actual Failure Path:                    v
[02:00 UTC Scheduled Trigger] ---> [Job Starts] ---> [Crash / Exception (Silent Failure)]
How to Fix It
To catch background job failures before they cause operational harm:
Enforce Tolerable Execution Windows: Define a strict time window within which a periodic job must complete. If a job fails to check in within its expected schedule, flag it as an incident immediately.
Monitor Exit Statuses: Ensure background scripts push execution metadata, metrics, and error logs upon completion or failure.
Summarizing the Monitoring Strategy
To protect your software operations against unexpected outages, your monitoring strategy must cover every layer of your stack:
Blindspot | Root Cause | Preventive Solution |
|---|---|---|
Shallow HTTP Checks | Relying solely on status codes ( | Payload verification, custom assertion scripts |
Transport Failures | Cert expirations, DNS/handshake latency | Proactive TLS chain validation, TTDR/TTFB timing analysis |
Geographic Isolation | Regional ISP issues, BGP routing errors | Multi-location synthetic probes executed in parallel |
Non-HTTP Blindspots | Focusing only on web protocols | Layer 4 protocol probes (TCP, UDP, TLS, custom protocols) |
Silent Cron Failures | Background jobs crashing without notice | Scheduled job tracking with tolerable time windows |
Streamline Your Infrastructure Health with Crystade
Eliminating monitoring blindspots does not require maintaining a complex maze of custom scripts and disparate monitoring tools.
Crystade provides a unified SaaS platform built specifically for comprehensive active monitoring and cron job tracking. Designed for modern engineering teams, Crystade delivers:
Multi-Protocol Active Monitoring: Monitor endpoints seamlessly using HTTP, HTTPS, TCP, TLS, and specialized application protocols.
Global Synthetic Probes: Execute concurrent health checks across multiple geographic locations to pinpoint regional network outages instantly.
Deep Protocol & TLS Analysis: Track detailed connection timing breakdowns (TTDR, TTFB, RTT) and receive automatic notifications before SSL/TLS certificates expire.
Programmable Check Evaluation: Write customizable assertion logic to validate complex API response bodies, headers, and payloads beyond simple status codes.
Cron Job Tracking: Monitor background tasks and scheduled scripts with configurable tolerable execution windows to catch silent job failures immediately.
Incident Management & Status Pages: Keep your team informed with actionable alerts and maintain transparent communication with your users through public status pages.
Whether you are hosting standard REST APIs, microservices, background worker queues, or protocol-specific infrastructure, Crystade gives you full visibility into your stack’s operational health.
Get started with Crystade today and take control of your infrastructure monitoring.
Share this post
Related Posts
Keep reading from this category

How to Monitor Model Context Protocol (MCP) Servers for AI Tools
Model Context Protocol (MCP) servers are the backbone of AI tool integrations, but silent failures can break your agents. Learn what to monitor and how Crystade’s active monitoring keeps your MCP infrastructure healthy.

Cloudflare Spectrum for Minecraft: Protect, Accelerate, Then Monitor with Crystade
Cloudflare Spectrum offers 477 Tbps DDoS defense and Anycast latency for Minecraft servers, but it doesn’t answer one critical question: is your server healthy? Discover how Crystade’s active monitoring for Minecraft protocol, TLS, and all stack layers completes your uptime strategy.

Monitoring WordPress Websites: Beyond Basic Uptime Checks
Learn how to monitor WordPress uptime, TLS certificates, database connections, and background cron jobs to prevent silent outages and maintain site reliability.